You publish a product page, and somehow Google finds three different versions of it. One with a trailing slash, one without, one with a tracking parameter tacked on the end. To you, it is the same page. To Google, it might be three separate pages competing against each other for the same ranking spot.
This is duplicate content, and it is one of the most common technical SEO problems businesses run into without even realizing it. At Ovitech, we find duplicate content issues on nearly every new client site we audit, often hiding in places nobody thought to check, like URL parameters, printer-friendly pages, or product variations.
The good news is that fixing duplicate content is usually straightforward once you know where to look. This guide walks through exactly what causes it, how it hurts your rankings, and the specific steps to clean it up and keep it from coming back.
What Are Duplicate Content Issues?
Duplicate content issues happen when the same or very similar content appears on more than one URL, either on your own site or across different sites entirely. Google sees each URL as a separate page, so when two pages say almost the same thing, the search engine has to decide which one to show in results.
This does not always mean someone copied and pasted content on purpose. Most duplicate content in SEO comes from technical setup problems rather than intentional copying. A single blog post accessible through five different URL variations counts as duplicate content, even though there is technically only one piece of writing behind it.
The core issue is that duplicate pages on a website confuse search engines about which version deserves to rank. Instead of one strong page collecting all the ranking signals, those signals get split across multiple weaker versions.
Why Duplicate Content Hurts Your SEO
Google has been clear that duplicate content does not usually trigger a direct penalty. But that does not mean it is harmless. The real damage happens indirectly, and it adds up.
Your ranking signals get diluted. When several URLs contain the same content, backlinks, social shares, and internal links pointing to that content get split between them instead of consolidating behind one strong page.
Google has to guess which version to rank. Search engines pick one version to show in results, and it is not always the one you would have chosen. Sometimes it is a parameter-loaded URL that looks messy in search results.
Crawl budget gets wasted. Search engines allocate a limited amount of time to crawling your site. If bots spend that time crawling five duplicate URLs instead of your genuinely new pages, your fresh content takes longer to get indexed.
User experience suffers too. Visitors landing on different versions of the same page, especially with inconsistent formatting or broken elements, lose trust in the site.
None of this means duplicate content will destroy your rankings overnight. But left unaddressed, it steadily works against your SEO in ways that are hard to trace back to the actual cause.
Common Causes of Duplicate Content
Before fixing anything, it helps to know exactly where duplicate URLs tend to come from. Here are the usual suspects.
URL Parameters
Tracking parameters, session IDs, and filter options often generate multiple URLs for what is essentially the same page. A product page might be accessible as /shoes and also as /shoes?color=black&sort=price, and Google treats these as different URLs unless told otherwise.
WWW vs Non-WWW and HTTP vs HTTPS
If your site is accessible at www.yoursite.com, yoursite.com, and both the HTTP and HTTPS versions of each, that is technically four separate versions of every page unless redirects are set up correctly.
Printer-Friendly or Alternate Versions
Some sites automatically generate printer-friendly or mobile-specific page versions with their own unique URLs, unintentionally creating duplicate pages on a website that Google indexes separately.
Ecommerce Product Variations
A product available in five colors sometimes generates five nearly identical pages, each with a different URL, but with content that barely changes beyond the color name.
Syndicated or Republished Content
Publishing the same article on your blog and on a partner site, or republishing an old post under a new URL without redirecting the original, creates duplicate content across domains, not just within your own site.
Scraped or Copied Content
Sometimes duplicate content is not your fault at all. Other sites scrape and republish your content without permission, which can create duplicate content SEO issues that are outside your direct control but still worth monitoring.
How to Fix Duplicate Content: Step by Step
Now the part that actually matters. Here is exactly how to fix duplicate content once you have identified where it is coming from.
Step 1: Run a Duplicate Content Checker
Before fixing anything, find out how much duplicate content actually exists on your site. Tools like Siteliner, Copyscape, and Screaming Frog can crawl your site and flag pages with significant content overlap. Google Search Console is also useful here, since it will sometimes show which pages Google considers duplicates under the “Page Indexing” report.
Step 2: Set Canonical Tags for Duplicate Content
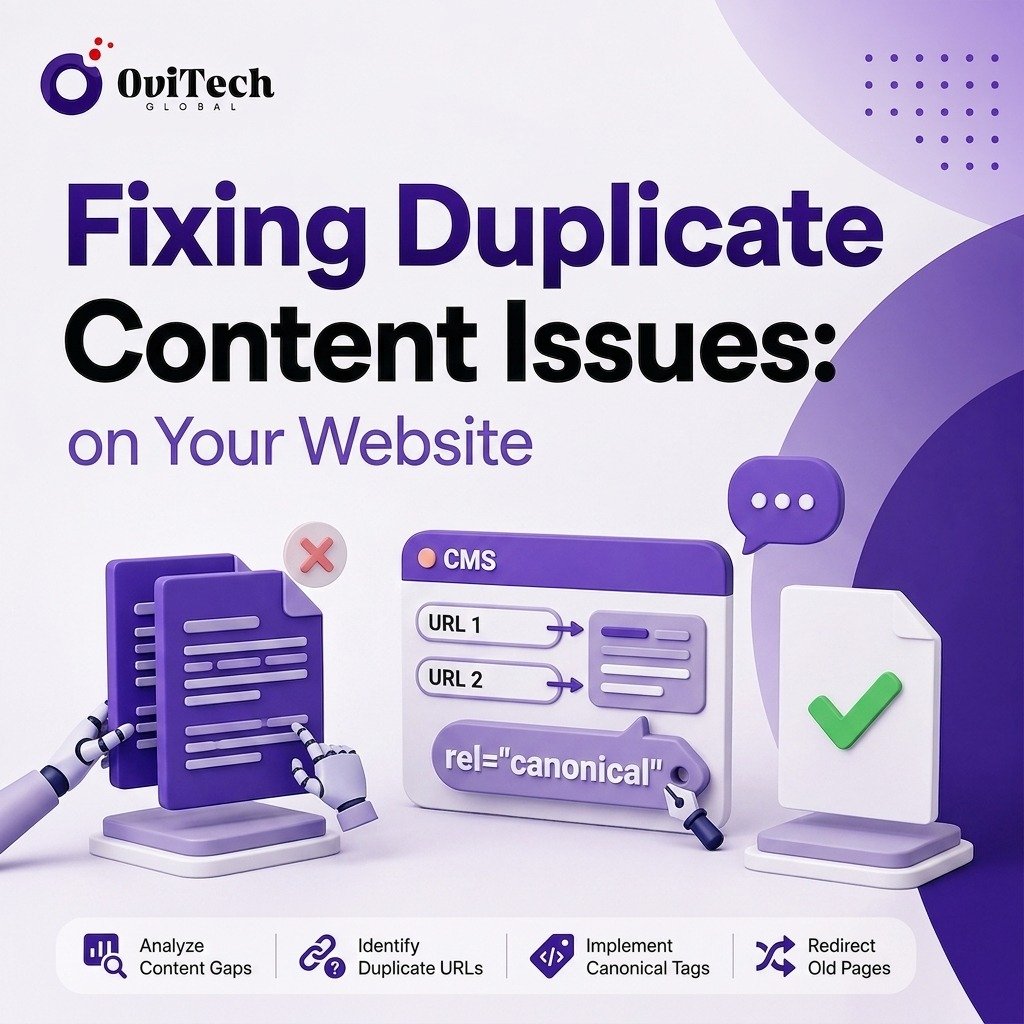
Canonical tags for duplicate content are the most common and effective fix for this problem. A canonical tag tells search engines which version of a page is the “real” one, even when multiple URLs technically exist.
Here is what a canonical tag looks like in HTML:
<link rel="canonical" href="https://yoursite.com/shoes/" />
Add this tag to the <head> section of every duplicate variation, pointing to the single URL you want indexed. If your site is on WordPress, most SEO plugins like Yoast or Rank Math handle this automatically, but it is worth checking manually on your most important pages.
Step 3: Redirect True Duplicates with a 301
If a duplicate URL serves no purpose and will never need to exist separately, a 301 redirect is often cleaner than a canonical tag. This physically sends both users and search engines to the correct URL rather than leaving two accessible versions in place.
Use this for cases like an old blog URL that got republished at a new address, or a WWW version of your site that should always redirect to the non-WWW version (or vice versa).
Step 4: Standardize Your URL Structure
Pick one version of your domain (with or without WWW, HTTP or HTTPS) and stick to it consistently. Set up a site-wide redirect so every variation funnels into your chosen version automatically. This single fix eliminates a large share of duplicate URL issues in one move.
Step 5: Handle Parameter-Based URLs
For sites with filtering, sorting, or tracking parameters, use canonical tags to point parameter-based URLs back to the clean version of the page. You can also configure parameter handling in Google Search Console to tell Google how to treat specific parameters.
Step 6: Rewrite Genuinely Similar Content
Sometimes duplicate content is not a technical URL issue at all. It is two pages that were written to say almost the same thing, like two blog posts covering overlapping topics. In this case, the fix is editorial: merge the two pages into one comprehensive piece, or rewrite one to focus on a distinctly different angle.
Step 7: Monitor for Scraped Content
If other sites are republishing your content without permission, use Google Search Console’s removal tool for the most serious cases, or reach out directly to request they add a canonical tag pointing back to your original page. This is less about fixing duplicate content SEO on your own site and more about protecting the content you have already published.
Comparison: Canonical Tag vs 301 Redirect for Duplicate Content
Choosing between these two fixes trips people up constantly. Here is a clear breakdown of when each one applies.
| Situation | Best Fix | Why |
|---|---|---|
| Both URL versions need to stay accessible | Canonical tag | Keeps both live while telling Google which one to index |
| One URL should disappear permanently | 301 redirect | Removes the duplicate entirely and passes ranking value |
| WWW vs non-WWW duplication | 301 redirect | Standardizes the domain across the whole site |
| Product filter or sort parameters | Canonical tag | Filters need to stay functional for users |
| Old blog post replaced by a new one | 301 redirect | Old URL is not needed anymore |
| Printer-friendly page versions | Canonical tag | Alternate format needs to remain accessible |
| Content syndicated to a partner site | Canonical tag (on partner’s page) | Original page stays live on your site |
If you are ever unsure which to use, ask a simple question: does this duplicate URL need to remain accessible to users for any reason? If yes, use a canonical tag. If no, use a redirect.
Real-World Example
An ecommerce client came to Ovitech with a site that had over 200 indexed URLs for what should have been around 60 actual product pages. The cause turned out to be a filtering system that generated a unique URL for every combination of size, color, and sort order, none of which had canonical tags pointing back to the main product page.
After adding canonical tags across the filtered URLs and cleaning up a handful of true duplicates with 301 redirects, Google’s indexed page count dropped to match the actual number of real pages within about six weeks. Rankings for the core product pages improved noticeably once their SEO signals were no longer split across a dozen filtered variations.
How to Prevent Duplicate Content Going Forward
Fixing existing duplicate content issues is only half the job. Preventing new ones from appearing is what keeps your site clean long-term.
- Set canonical tags as a standard part of your page publishing checklist, not an afterthought.
- Choose one URL format (WWW or non-WWW, trailing slash or not) and enforce it site-wide.
- Review new plugins or ecommerce features for how they generate URLs before launching them.
- Run a duplicate content checker every few months, especially after major site changes.
- Avoid publishing the same article on multiple platforms without a canonical tag pointing to the original.
A quick quarterly check with a crawler tool catches most duplicate content problems before they have a chance to affect rankings.
FAQs About Duplicate Content Issues
Q1: Does Google penalize websites for duplicate content?
Google does not issue a direct penalty for most duplicate content, since it understands that much of it is unintentional or technical in nature. The real cost comes from diluted ranking signals and wasted crawl budget, not a manual penalty. The exception is if content is duplicated deliberately to manipulate rankings, which can trigger a manual action.
Q2: How much duplicate content is considered a problem?
There is no exact percentage that triggers an issue, but a general guideline is that if a large portion of a page’s content matches another page word for word, it is worth addressing. Even partial overlap across many pages, like repeated boilerplate text, can add up to a meaningful problem across a large site.
Q3: Can duplicate content happen even if I never copy and paste anything?
Yes, and this is actually the most common cause. Technical issues like URL parameters, WWW versus non-WWW versions, and printer-friendly pages create duplicate URLs without anyone manually copying content. Most duplicate content SEO problems are structural, not editorial.
Q4: What is the fastest way to check for duplicate content on my site?
Running a crawl with a duplicate content checker like Screaming Frog or Siteliner is the quickest way to get a full picture. For a faster spot check, search Google using a unique sentence from your page in quotation marks and see how many URLs return that exact phrase.
Q5: Should I use a canonical tag or noindex for duplicate pages?
Use a canonical tag when the duplicate page should stay accessible to users but should not compete for rankings. Use a noindex tag when the page has no value to search engines at all, like an internal search results page or a thank-you page. Canonical tags consolidate ranking signals, while noindex simply removes a page from search results entirely.
Q6: How long does it take for a duplicate content fix to show results?
Once canonical tags or redirects are in place, Google typically needs a few weeks to recrawl the affected URLs and update its index accordingly. Larger sites with more URLs to process may take longer. Checking back in Google Search Console after four to six weeks usually gives a clear picture of whether the fix worked.
Q7: Can duplicate content across different domains hurt my rankings?
If someone else copies your content and republishes it elsewhere, it is less likely to hurt your own rankings directly, since Google generally identifies the source. That said, it is still worth addressing, since a poorly handled case can occasionally cause confusion about which source is authoritative, especially if the copying site has stronger overall authority than yours.
Q8: Do duplicate product variations on ecommerce sites always need separate URLs?
Not always. If the variations differ only slightly, like color options with identical descriptions, consider using a single URL with a selectable variant option instead of generating a new page for each one. When separate URLs are necessary for business reasons, canonical tags pointing to the primary product page keep the SEO signals consolidated.